Xingyu Chen

Assistant Professor at Zhongguancun Academy

Xingyu Chen

I lead ZGCA HMI Lab, working on Interaction-centric Embodied AI.

I am currently an Assistant Professor at Zhongguancun Academy. Previously, I was an assistant research fellow at Peking University and IDEA-CVR, working closely with Prof. Lei Zhang.

Before joining PKU, I spent 4 years in industry at Kuaishou and Xiaobing, working closely with Dr. Baoyaun Wang. I received my Ph.D. from the Institute of Automation, Chinese Academy of Sciences in 2020 under Prof. Junzhi Yu, and my B.S. from Chengdu University of Technology in 2015.

For Ph.D. students and research interns

If you are interested in ZGCA and my research directions, please contact me.

Get in touch

Research Areas

My work sits at the intersection of computer vision, robotics, graphics, and human-machine interaction.

Near-field Interaction

Scene Interaction Parsing, Hand-Object Interaction Prediction, Manipulation Model.

Spatial Interaction

Spatiotemporal State Representation, Controllable World Model, Navigation Model.

Social Interaction

Human-Robot Collaboration Framework, Human-Robot Social Interaction Framework, Multi-Embodied Agents.
Selected Publications

Full publications
arXiv 2026

PINT: A Unified Model with Shared Predictive Intent for Robot Manipulation

Xinyu Guo, Chao Jing, Li Yi, Xingyu Chen, Zhengxing Wu

PINT is a unified model that leverages shared predictive intent for robot manipulation tasks.

arXiv 2026

4D Latent Cache for Efficient Conditioning in Dynamic World Modeling

Jianhui Zhang, Zuyao Lin, Pengxin Xu, Jingdong Wang, Xingyu Chen

4LC reuses cached visual representations across time and viewpoints to condition multi-task video generation efficiently.

NeurIPS 2026

HyrCAP: Hybrid Rank-Calibration of Action Proposals for Temporal Event Understanding

Rui Chen, Xingyu Chen, Pengxin Xu, Kai Chen, Junzhi Yu

Hybrid propose rank-calibration method for of action proposal and semantic understanding.

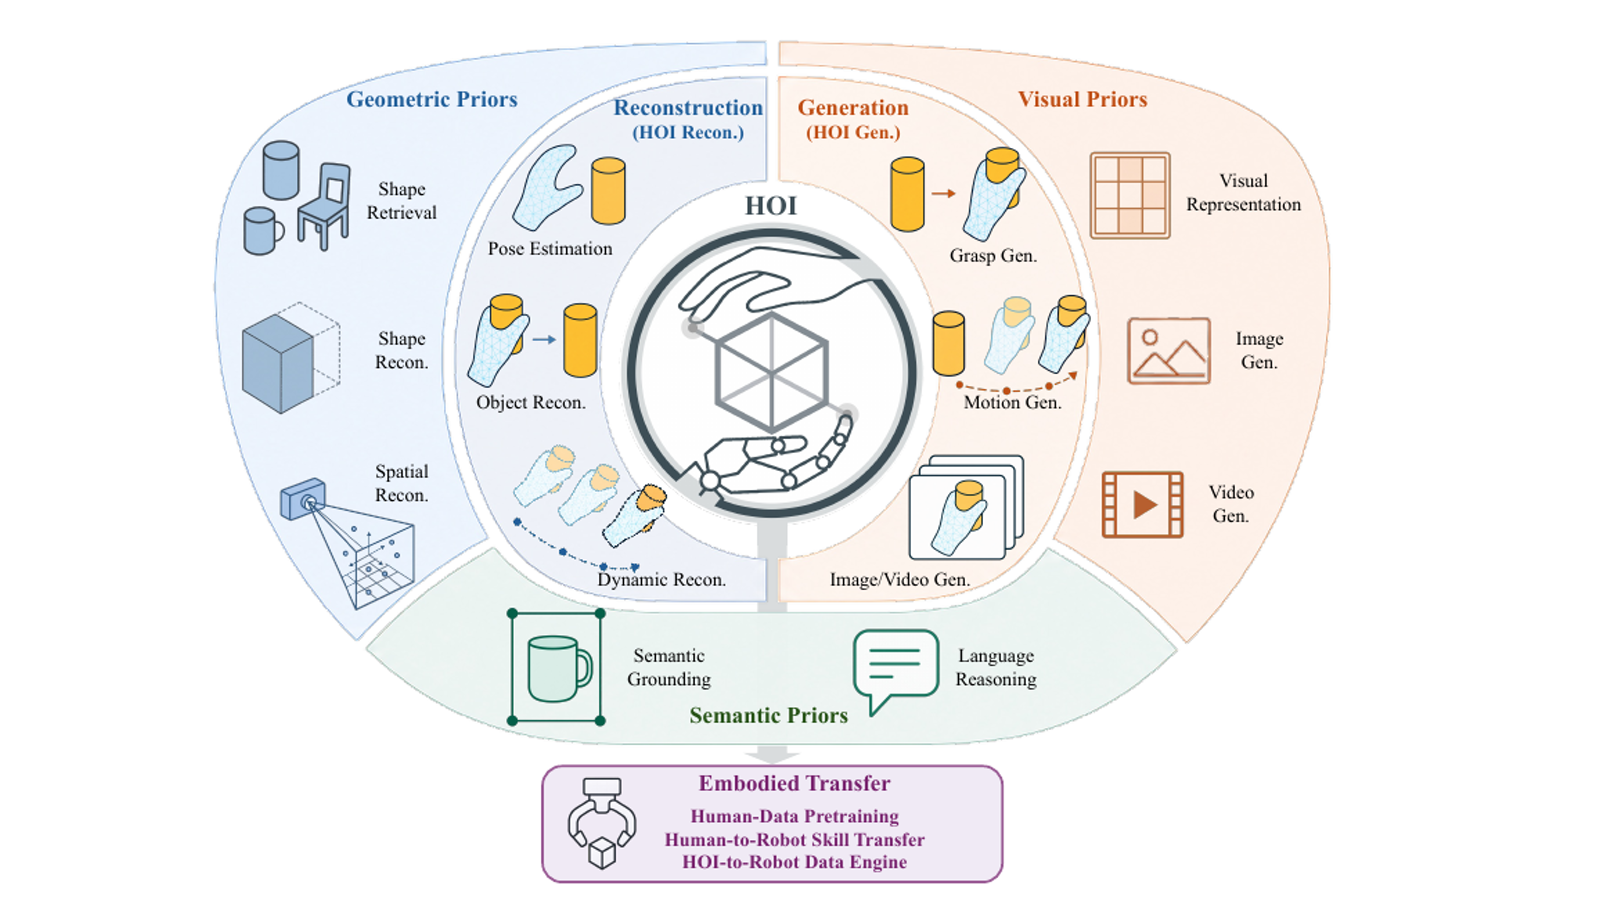
HOI Survey preview
arXiv 2026

Hand-Object Interaction in the Age of Large Foundation Models: Reconstruction, Generation, and Embodied Transfer

Weiquan Lin, Yu Deng, Shiyang Liu, Luping Xiao, Xu Tang, Junzhi Yu, Jiaolong Yang, Lei Zhang, Xingyu Chen

A systematic survey of foundation-model priors for HOI reconstruction, generation, and embodied transfer.

NeurIPS 2026

PriorVLA: Prior-Preserving Adaptation for Vision-Language-Action Models

Xinyu Guo, Bin Xie, Wei Chai, Xianchi Deng, Tiancai Wang, Zhengxing Wu, Xingyu Chen

Prior knowledge maintenance and efficient downstream fine-tuning in VLA models.

arXiv 2026

World-Ego Modeling for Embodied Video Generation in Long-Horizon Navigation-Manipulation Tasks

Zuyao Lin, Jianhui Zhang, Peidong Jia, Xiaoguang Zhao, Shanghang Zhang, Jingdong Wang, Xingyu Chen

A video-based world-ego modeling framework for long-horizon evolution in hybrid embodied tasks.

VLingNav preview
TRO 2026

VLingNav: Embodied Navigation with Adaptive Reasoning and Visual-Assisted Linguistic Memory

Shaoan Wang, Yuanfei Luo, Xingyu Chen, Aocheng Luo, Dongyue Li, Chang Liu, Sheng Chen, Yangang Zhang, Junzhi Yu

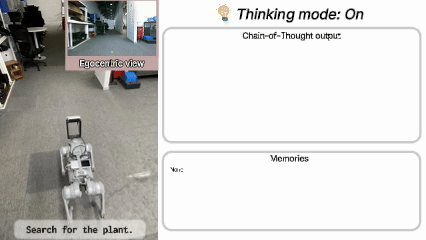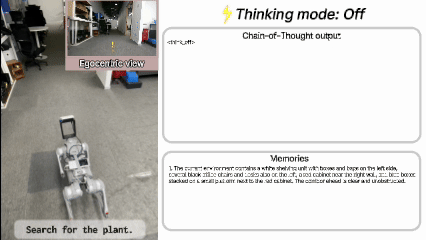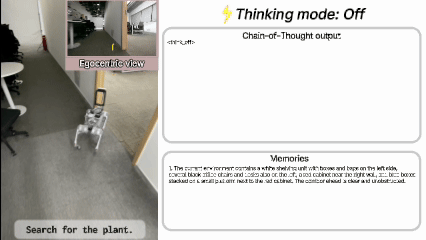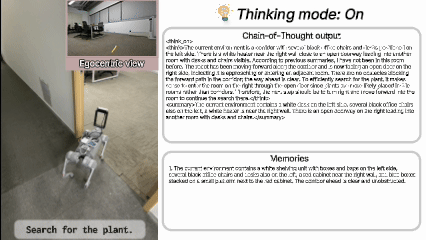
VLingNav combines adaptive reasoning with visual-assisted linguistic memory for persistent cross-modal semantic memory in long-horizon navigation.

Detect Anything via Next Point Prediction preview
CVPR 2026

Detect Anything via Next Point Prediction

Qing Jiang, Junan Huo, Xingyu Chen, Yuda Xiong, Zhaoyang Zeng, Yihao Chen, Tianhe Ren, Junzhi Yu, Lei Zhang

A unified framework for point-based visual cognition based on LLMs.

Rex-Thinker preview
ICLR 2026

Rex-Thinker: Grounded Object Refering via Chain-of-Thought Reasoning

Qing Jiang, Xingyu Chen, Zhayang Zeng, Junzhi Yu, Lei Zhang (* for equal contribution)

Object referring is reformulated as a Chain-of-Thought reasoning task that verifies candidate object regions step by step.

HandOS preview
CVPR 2025

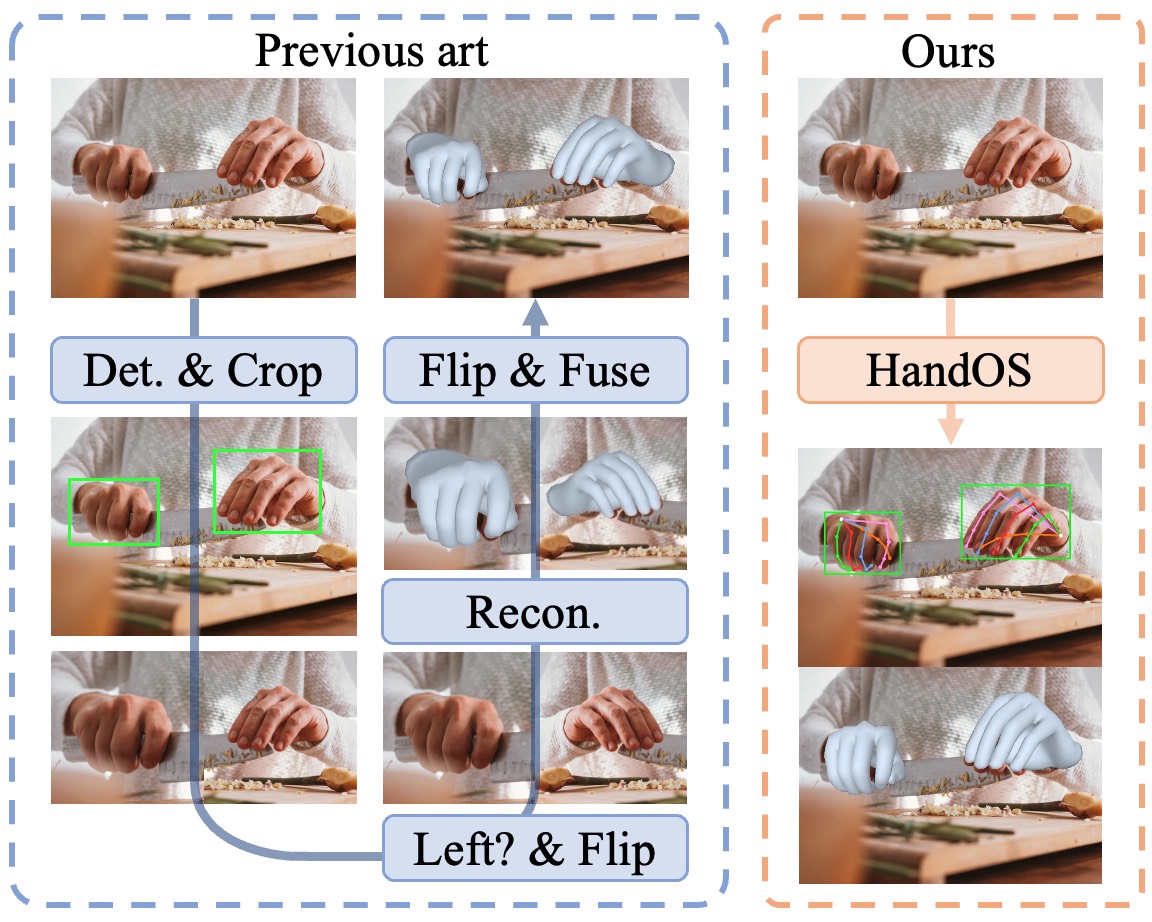
HandOS: 3D Hand Reconstruction in One Stage

Xingyu Chen, Zhuheng Song, Xiaoke Jiang, Yaoqing Hu, Junzhi Yu, Lei Zhang

An end-to-end framework for hand detection, 2D pose estimation, and 3D mesh reconstruction with a unified hand representation.

arXiv 2024

DINO-X: A Unified Vision Model for Open-World Object Detection and Understanding

IDEA Research Team

A unified framework for visual perception.

CVPR 2024

HAVE-FUN: Human Avatar Reconstruction from Few-Shot Unconstrained Images

Xihe Yang, Xingyu Chen, Shaohui Wang, Daiheng Gao, Xiaoguang Han, Baoyuan Wang

A framework for creating human avatars from few-shot unconstrained images.

ICCV 2023

Mimic3D: Thriving 3D-Aware GANs via 3D-to-2D Imitation

Xingyu Chen, Yu Deng, Baoyuan Wang

A 3D-aware GAN that can directly render high-resolution images.

CVPR 2023

Hand Avatar: Free-Pose Hand Animation and Rendering from Monocular Video

Xingyu Chen, Baoyuan Wang, Heung-Yeung Shum

A neural hand rendering framework with self-occluded illumination.

MobRecon preview
CVPR 2022

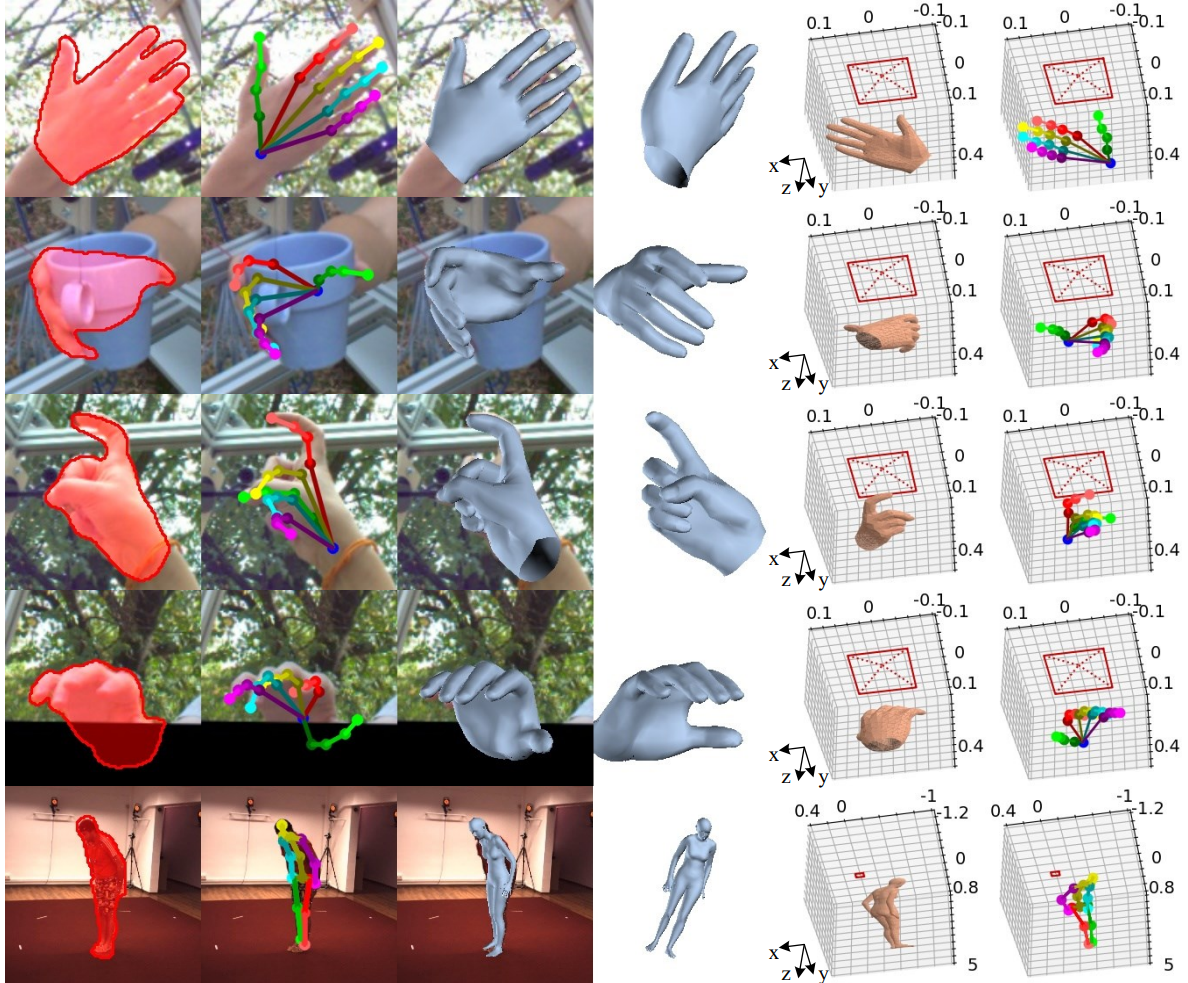
MobRecon: Mobile-Friendly Hand Mesh Reconstruction from Monocular Image

Xingyu Chen, Yufeng Liu, Yajiao Dong, Xiong Zhang, Chongyang Ma, Yanmin Xiong, Yuan Zhang, Xiaoyan Guo

A single-view hand mesh reconstruction framework with accuracy, fast inference, and temporal coherence.

Camera-Space Hand Mesh Recovery preview
CVPR 2021

Camera-Space Hand Mesh Recovery via Semantic Aggregation and Adaptive 2D-1D Registration

Xingyu Chen, Yufeng Liu, Chongyang Ma, Jianlong Chang, Huayan Wang, Tian Chen, Xiaoyan Guo, Pengfei Wan, Wen Zheng

A camera-space mesh recovery method that separates root-relative mesh recovery and root recovery.

Complete Publication Record

Browse first- or corresponding-author papers, co-author papers, and book in the redesigned full publication page.

Open Full Publications